Benchmark results & proofs
Benchmark evaluations and OpenAI research problems formally verified with Turing Agent.
Benchmark results
Theorem formalization is measured on the 143 problems of Formal TCS Bench (statements from recent TCS papers). A submission succeeds only if it compiles and passes independent semantic review. Proof formalization uses 248 theorems from the PFR and TestingLowerBounds (TLB) projects in RLMEval; success means a Lean proof with no sorry.
Each model is run as direct generation, inside Codex CLI, inside Claude Code, and inside Turing Agent. All numbers are pass@1 with one final submission per problem.
Pass@1 (%). Underlined: best in column. PFR covers additive combinatorics and entropy methods (Polynomial Freiman–Ruzsa); TLB covers information-theoretic lower bounds for hypothesis testing.
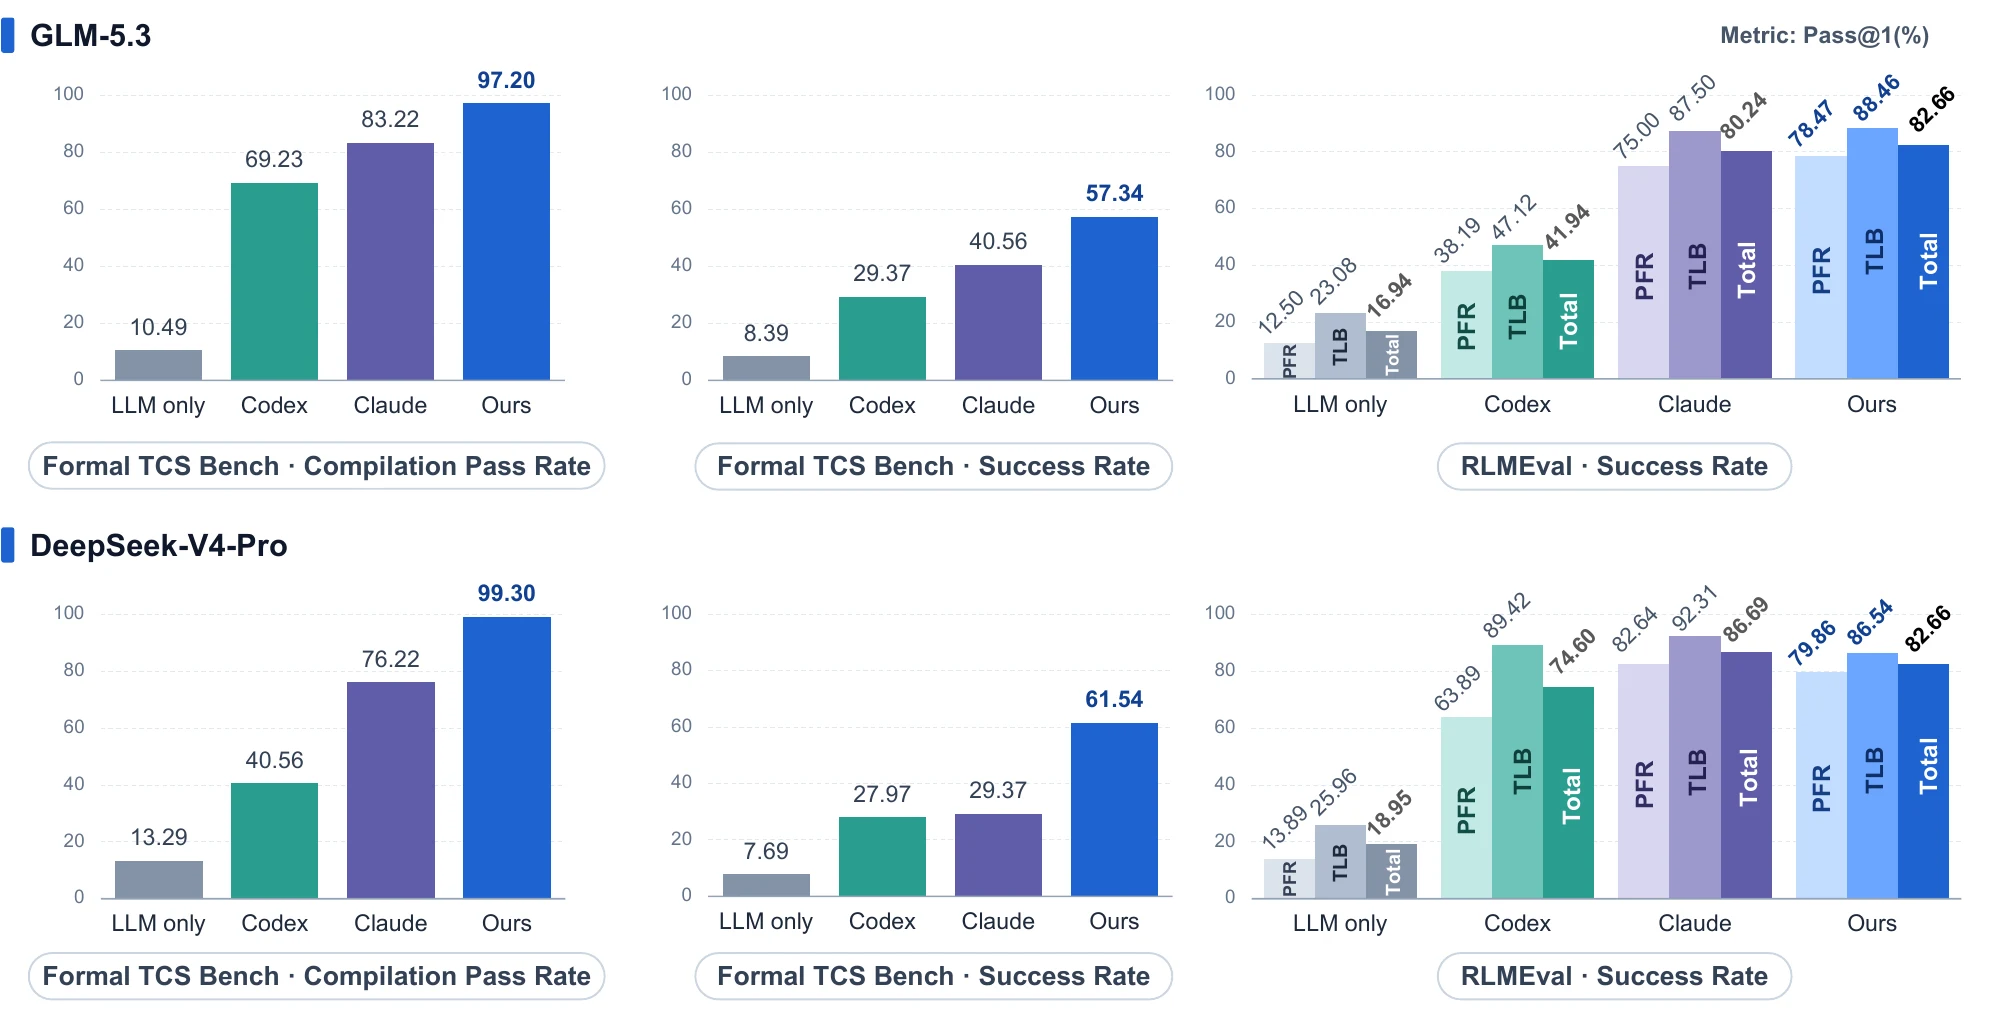
With GLM-5.3 and DeepSeek-V4-Pro, Turing Agent reaches 57.34% and 61.54% success on Formal TCS Bench — 16.78 and 32.17 points above Claude Code, the strongest baseline — with compilation rates of 97.20% / 99.30%. The gap between compiling and being faithful is exactly why semantic review is evaluated separately.
On RLMEval it exceeds 82% overall with both models: 82.66% with GLM-5.3 (best of all methods, 2.42 points above Claude Code) and 82.66% with DeepSeek-V4-Pro, 8.06 points above Codex CLI and within 4.03 points of Claude Code.
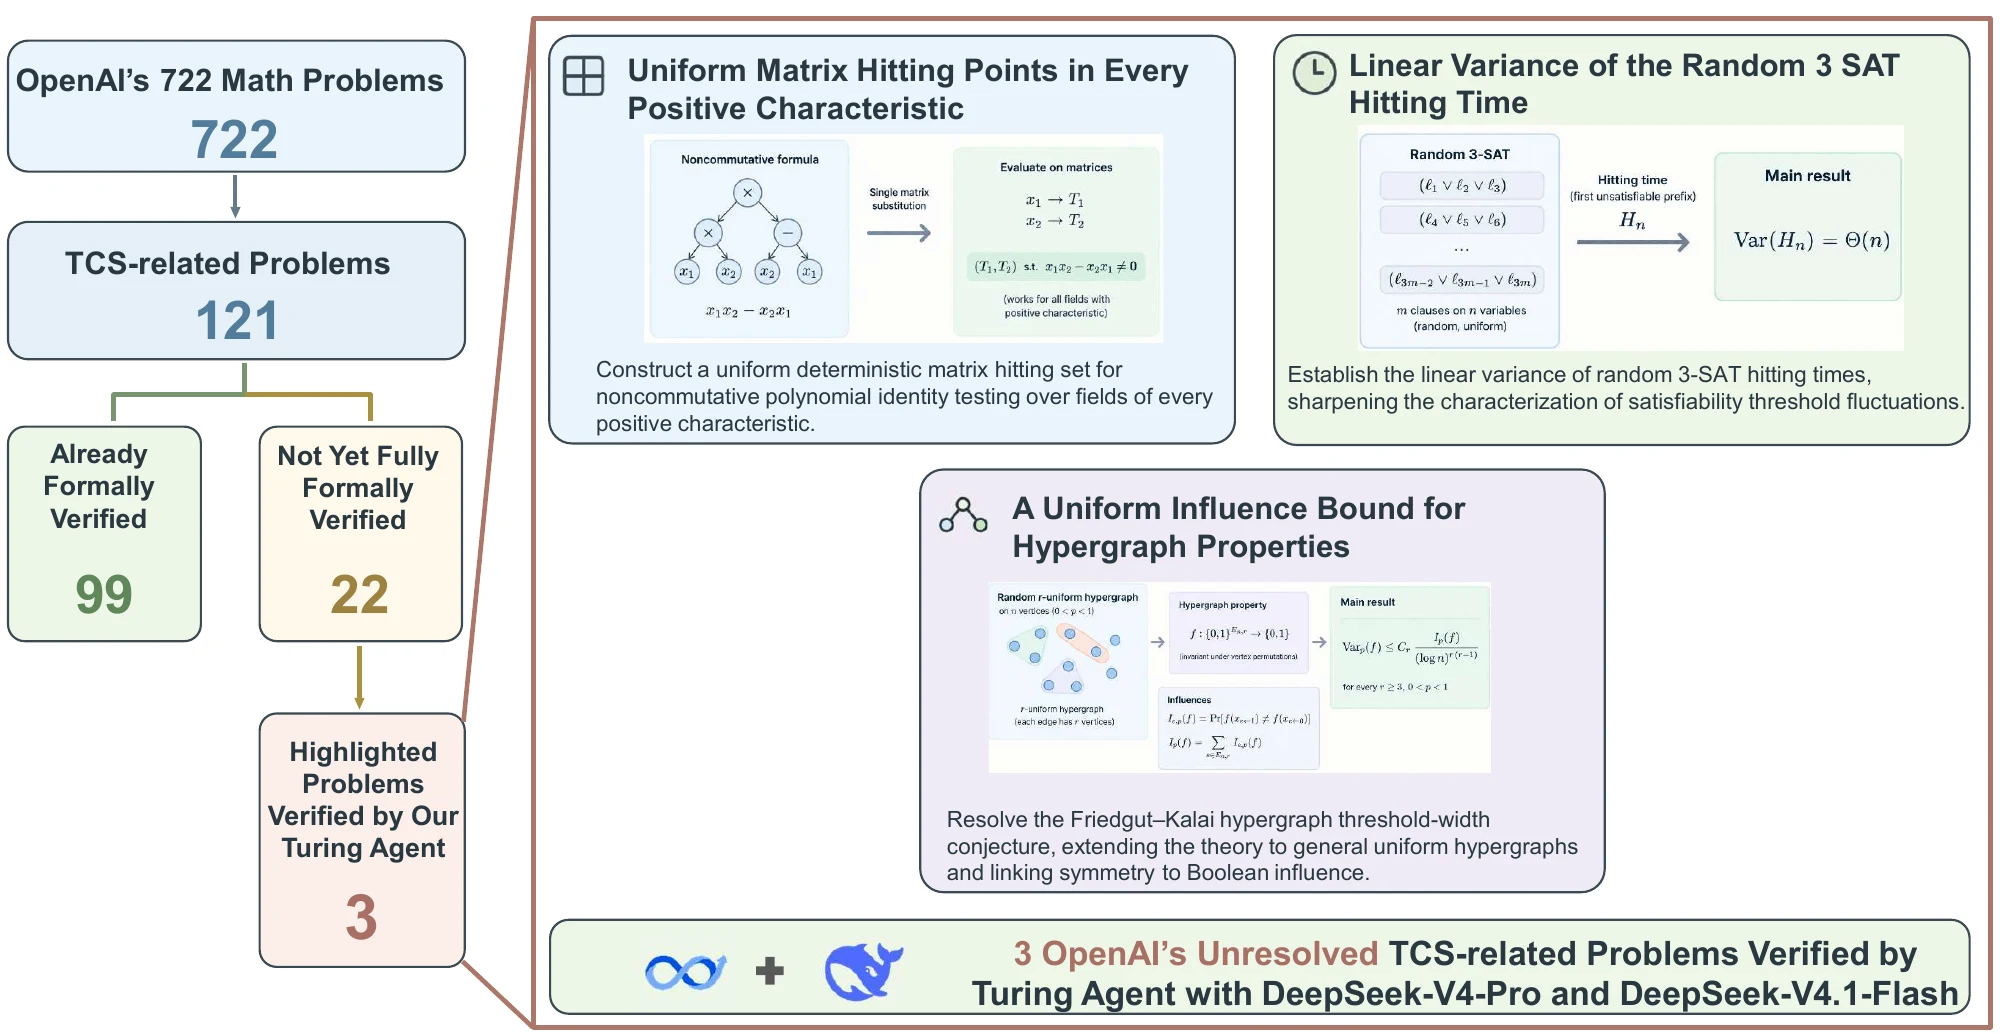
OpenAI research problems
We highlight 3 problems from OpenAI's research collection, with Lean-kernel-checked proofs produced by Turing Agent using DeepSeek-V4-Pro and DeepSeek-V4.1-Flash.